Notes from a one-person GPU lab.
Dated, versioned write-ups of experiments run on a small private GPU fleet: kernel ports to new silicon, model surgery, measurement methods, and the infrastructure underneath. Every note links the code and the pull requests.
November 2026
MAGI-2 Preview on one B300
Sand AI's MAGI-2 Preview ships with Hopper-only kernels. After replacing them for Blackwell, I measured where its 110,592 experts send their tokens (no dead ones, flat utilisation), tried pruning half of them (coherent clips, but a 10x larger one-step error than the kernel noise floor), and packed the 217 GB of expert weights to NVFP4 instead (1.6x the floor). The preview model now runs on a single B300 at 5.5 s per denoise step, and the full 1080p pipeline fits there too. Three pull requests carry the port, the FP4 path and the prompt-enhancement fixes upstream.
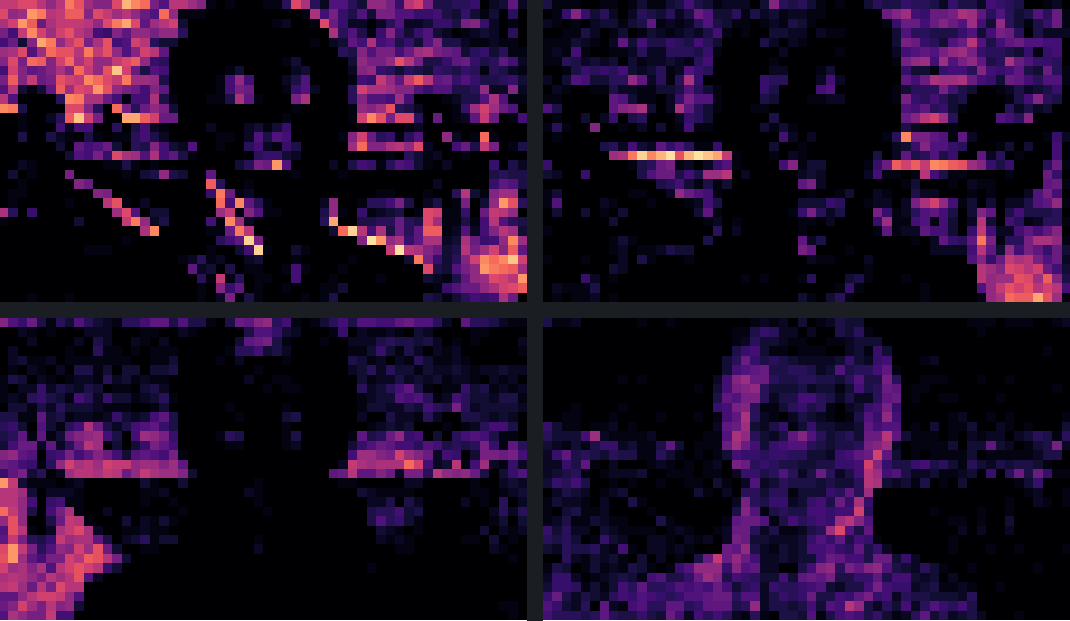
Where four experts of one MoE head fire across a frame at mid-denoise. Routing is semantic: one expert owns the silhouette, others the background, the edges and a highlight.
an HGX 8x B300 (sm_103), using two to four GPUs per run
-
November 2026
MAGI-2 Preview on one B300
Sand AI's MAGI-2 Preview ships with Hopper-only kernels. After replacing them for Blackwell, I measured where its 110,592 experts send their tokens (no dead ones, flat utilisation), tried pruning h...